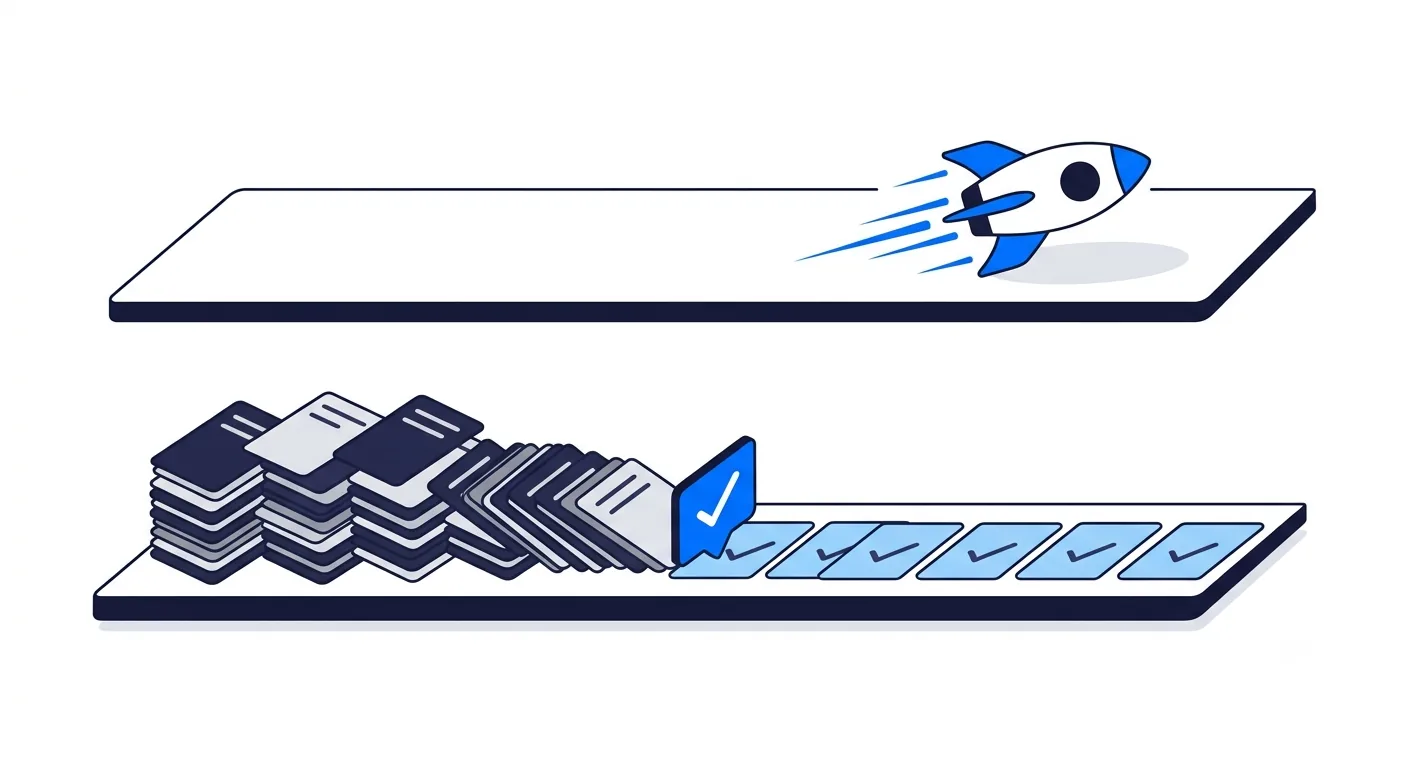
Every engineering team has a backlog that keeps growing no matter how good the sprint planning is. Flaky tests nobody has time to fix. A migration everyone agrees is overdue. Bug reports that pile up while the roadmap gets all the attention. Clearing that backlog usually means pulling one of your best engineers off the product work you actually need them building, which is why it almost never happens. This post is about the other option: bringing in a dedicated remote engineer whose whole job is the backlog, so your core team never has to choose between fixing the past and building the future.
Why does the backlog never actually get cleared?
Not because nobody cares. Because every item in the backlog loses to whatever is on the roadmap this quarter, every single sprint planning session. Your best engineers are the ones capable of clearing it fastest, and they are also the ones you need most on the new feature the CEO promised a customer. The backlog is not urgent today, so it gets pushed to next sprint. Then the sprint after that. Eighteen months later it is 300 items deep and everyone has quietly stopped believing it will ever shrink.
The honest fix is not "try harder to prioritize it." It is separating the person who clears the backlog from the person who ships the roadmap, so the two stop competing for the same hours.
Why does hiring someone for this feel risky?
Because most hiring decisions are framed as a permanent commitment before you have any evidence the fit is right. A full-time hire means a role definition, a headcount approval, months of onboarding before they are useful, and a hard conversation if it does not work out. Founders and engineering leads avoid that risk by doing nothing, which means the backlog keeps growing and the actual cost, in slower fixes, accumulating tech debt, and burned-out senior engineers, keeps growing with it.
The lowest-risk way to solve this is to flip the order: prove the fit on bounded, well-scoped backlog work first, then decide whether to expand the engagement. You are not signing up to restructure your team. You are handing someone a list of things that need doing and watching what happens.
How does a backlog-focused engagement actually work?
It starts with a scoping call where you and the engineer walk through the actual backlog, not a hypothetical role description. You pick a defined slice: the flaky test suite, the dependency upgrade nobody wants to touch, the 20 oldest open bugs, the migration that has been "next quarter" for three quarters. That becomes the engagement's first block of work, with a clear definition of done.
From there:
- The engineer gets read access and context first. Codebase walkthrough, existing docs, a session with whoever owns the area. No blind commits on day one.
- Work ships in small, reviewable pull requests. Your team reviews the same way they would review any other contributor's code. Nothing merges without your standards being met.
- Your core team stays untouched. They keep shipping the roadmap. The backlog work happens in parallel, not by borrowing their time for reviews beyond normal PR review.
- You get a running log of what got closed. Not vague status updates. Actual ticket numbers, actual merged PRs, actual test coverage that went from red to green.
This is the same dedicated-engineer model we use for roadmap work, detailed in how we work, just pointed at your backlog instead of your next feature.
What kind of backlog work fits this model, and what doesn't?
Fits well:
- Test coverage and flaky test cleanup
- Dependency and framework version upgrades
- Bug triage and closure on well-documented issues
- Performance and query optimization tickets that keep getting deprioritized
- Incremental refactors of a module everyone avoids touching
- Migrations with a known target state (database, cloud provider, framework version)
Fits poorly:
- Undefined "make it better" work with no acceptance criteria
- Anything requiring deep, unwritten institutional knowledge only one person on your team has, and that person has no time to transfer it
- Net-new product features that need constant product input, not a backlog item, a roadmap item
If your backlog is mostly the first list, this model works well. If it is mostly the second list, you need a scoping conversation before an engagement, not after one.
How is this different from just hiring a full-time dedicated developer?
It is not a different model, it is a different starting scope. A backlog-focused engagement is deliberately narrow and deliberately measurable: a defined list, a defined done state, a short runway before you evaluate. A full dedicated hire is an open-ended commitment to your roadmap. Many engagements start as the first and become the second once the trust is established and the engineer has proven the fit, the same reasoning we cover in our full comparison of dedicated developers, freelancers, and agencies. Starting narrow is not a lesser version of hiring, it is the responsible way to de-risk a decision you would otherwise be making on faith. We break down exactly how to structure that kind of trial in the low-risk way to trial a dedicated developer before you commit.
What does the first two weeks actually look like?
Week one is context, not output. Codebase access, a walkthrough with your team, and the engineer picking off the first two or three items from the agreed list. You should expect small, reviewable PRs starting within the first few days, not a two-week silence followed by one giant merge.
Week two is rhythm. The engineer is working through the backlog independently, async updates land in your existing tools (Slack, Linear, Jira, whatever you already run), and your core team's involvement is limited to normal code review, the same as reviewing any other engineer's PRs. By the end of week two you should have a concrete, visible list of what got closed and a clear read on whether the fit is right.
How do you know if it's actually working?
Look for evidence, not vibes:
- Tickets closed against the agreed list, with linked PRs your team reviewed and approved
- Code quality your senior engineers would have signed off on if they had written it themselves
- Zero disruption to your core team's roadmap velocity during the engagement
- Communication that does not require you to chase status updates
If those four hold up over the first few weeks, you have your answer on whether to expand the scope, whether toward more backlog work, a specific new feature, or a full dedicated role. If they do not, you have lost a small, defined block of time, not a year of headcount you cannot walk back.
The verdict
Backlogs pile up because clearing them competes with the roadmap for the same engineers, and the roadmap always wins. The fix is not asking your core team to work harder, it is giving the backlog its own dedicated owner, someone whose full-time job is closing the list your team has not had time for. Start narrow, measure the output against a real list, and only expand the engagement once you have evidence, not promises. If you want to see what a defined backlog engagement would look like for your stack, whether that is full stack, backend, or something more specific, talk to us and bring your actual backlog to the call.